Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) Exam Topics and Questions
These Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) exam topics are organized according to official exam domains to help candidates quickly verify coverage and focus on assessment rather than theory. Each domain is paired with topic-wise Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) sample questions that reflect how objectives are tested in the actual exam. This structure enables efficient review, targeted self-assessment, and rapid identification of weak areas when preparing for the Salesforce Certified MuleSoft Platform Architect certification exam.
Let's Practice Free Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) Questions Aligned with Official Exam Topics
This topic sets the conceptual floor for the entire exam. Every later decision about deployment, governance, and data modelling rests on how clearly you understand what an application network is and how API-led connectivity differs from point-to-point or ESB-style integration. The trap here is assuming familiarity is enough: the exam tests precise distinctions, not general awareness. Candidates who skim this area lose marks on questions that look easy until the options are close together. – Technologies and the API-led model...
This topic sets the conceptual floor for the entire exam. Every later decision about deployment, governance, and data modelling rests on how clearly you understand what an application network is and how API-led connectivity differs from point-to-point or ESB-style integration. The trap here is assuming familiarity is enough: the exam tests precise distinctions, not general awareness. Candidates who skim this area lose marks on questions that look easy until the options are close together.
– Technologies and the API-led model
API-led connectivity sits alongside other integration patterns, and the exam expects you to tell them apart under pressure. You need to know what makes an API-led approach different from a service bus or a direct connection, and why those differences matter for reuse and change management. The distinction between synchronous and asynchronous styles, and between REST, SOAP, and event-based approaches, feeds directly into tier-assignment questions. When the exam gives you a scenario and asks which technology fits, it is testing whether you can match a capability to a real constraint, not whether you can define the term.
– Web APIs, tiers, and Anypoint Platform components
The three-tier model (System, Process, Experience) is load-bearing throughout the exam. This topic introduces the ownership, functional focus, and rate-of-change criteria that determine which tier an API belongs to. Get those criteria wrong here and you will keep getting layer-assignment questions wrong in later topics. Web APIs carry specific characteristics around discoverability, statelessness, and contract stability that the exam uses to test whether you understand what makes an API a first-class integration asset rather than a private internal call. Anypoint Platform is introduced at the component level here: the exam wants you to recognise what each high-level piece does (Design Center, Exchange, API Manager, Runtime Manager) without yet diving into configuration. Knowing the purpose of each component prevents you from confusing their roles when later topics assume you can distinguish them.
How Explaining application network basics is tested
At 7%, this topic contributes a focused set of items that tend to appear early in the exam and calibrate how you handle everything that follows. Items typically present a short integration scenario and ask you to identify the correct technology, pattern, or tier assignment. The difficulty is that the distractors are plausible: a SOAP service can look like a System API, and an event-driven pattern can look like async REST. Items reward precise recall of the criteria that separate these choices, particularly ownership boundaries and rate of change. Candidates lose marks by applying informal reasoning rather than the specific attributes the API-led framework defines. The Anypoint Platform component questions reward knowing what each component is responsible for at a high level; they do not yet require configuration knowledge. The biggest trap is treating tier assignment as intuitive when it is actually rule-based: the exam will construct scenarios where the intuitive answer is wrong and the criteria-based answer is right.
The ITExamsTopics practice test covers all nine exam topics, including this foundational one. Running through the full bank before you sit lets you see exactly which tier-assignment and technology-distinction items catch you out, so you can close those gaps rather than guess at them on exam day.
The question below tests one of the precise distinctions this topic introduces. Work through it before reading on.
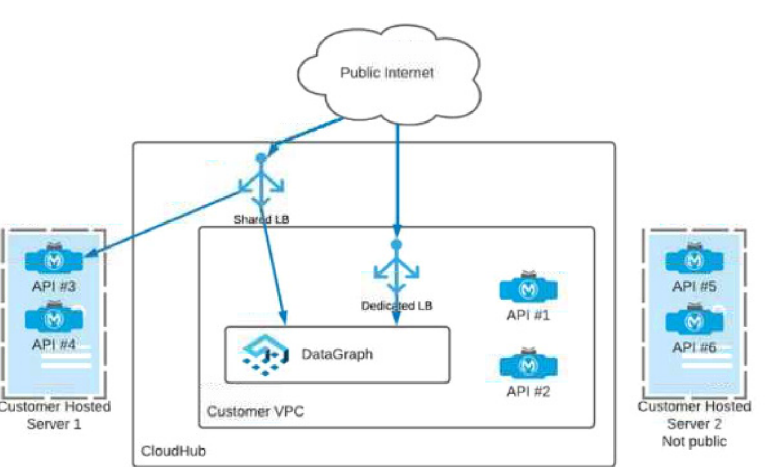
Which APIs can be used with DataGraph to create a unified schema?
Where the previous topic explained what an application network is, this one asks who runs it and on what infrastructure. The organizational and platform decisions made here shape every governance and deployment choice that follows. At 10%, it carries enough weight that a weak understanding of hosting models or identity management can cost you several marks. The exam is especially interested in whether you can map a set of organizational constraints to the right platform configuration. – The Center for...
Where the previous topic explained what an application network is, this one asks who runs it and on what infrastructure. The organizational and platform decisions made here shape every governance and deployment choice that follows. At 10%, it carries enough weight that a weak understanding of hosting models or identity management can cost you several marks. The exam is especially interested in whether you can map a set of organizational constraints to the right platform configuration.
– The Center for Enablement and MuleSoft Catalyst
The C4E is not just an org chart box: the exam tests whether you know what it is designed to produce, how you measure whether it is working, and what KPIs signal success versus stagnation. Questions in this area will give you a description of an organization and ask which KPIs are appropriate or which C4E structure fits. MuleSoft Catalyst provides a structured delivery methodology, and the exam expects you to describe its high-level structure and the benefits it offers to an implementation programme. The trap is treating both as abstract concepts: the exam anchors them in scenarios where you must recommend one approach over another based on specific organizational characteristics.
– Hosting, identity, and data residency
Anypoint Platform can be hosted and managed in several configurations, and the exam wants you to choose between them based on stated requirements around control, compliance, and operational model. The control plane and runtime plane are distinct, and where each one runs has direct consequences for data residency. Speaking of which, data residency is an explicit sub-topic: you need to know which categories of data (payload, metrics, and others) live where under each hosting option, because a wrong assumption here can violate a compliance requirement in the scenario. Identity Management and Client Management are related but different: Identity Management handles who the human user is, Client Management handles which application is calling. The exam will give you an OAuth or SAML scenario and expect you to select the right option for each role. Conflating the two is a reliable way to drop marks.
How Establishing organizational and platform foundations is tested
Items in this topic tend to be scenario-driven: you are given a description of an organization's size, compliance requirements, or operational preferences, and you must recommend a hosting model, an identity configuration, or a set of C4E KPIs. The weight of 10% means you will see enough of these to feel the impact of any systematic gap. Candidates lose marks in two main ways. First, they confuse the control plane and the runtime plane, leading to wrong answers on data residency and network topology questions. Second, they treat Identity Management and Client Management as interchangeable, which produces wrong selections whenever the scenario specifies an OAuth flow or a client credential requirement. Items reward the ability to match a constraint (data sovereignty, on-premises connectivity, federated identity) to the platform option that satisfies it. Knowing the high-level structure of MuleSoft Catalyst matters here too: questions will not ask you to recite it, but they will assume you can recognise which phase or element applies to a given situation.
Working through the ITExamsTopics question bank topic by topic lets you check your coverage of hosting models and identity options against a realistic item set, rather than discovering a gap when the real exam is already in front of you.
The question below focuses on one of the platform configuration decisions covered in this topic. Take a moment to work through it carefully.
What is a typical result of using a fine-grained rather than a coarse-grained API deployment model to implement a given business process?
Good API design is where architecture intention meets implementation reality. This topic moves from the platform's structural concepts into the hands-on decisions that determine whether an API can be versioned, reused, and consumed safely. At 10%, it demands precision on semantic versioning rules, bounded context mapping strategies, and the dependency chain from specification to client. These are areas where candidates often have practical experience but find the exam's formal distinctions harder than expected. – Specifications, assets, and the dependency chain...
Good API design is where architecture intention meets implementation reality. This topic moves from the platform's structural concepts into the hands-on decisions that determine whether an API can be versioned, reused, and consumed safely. At 10%, it demands precision on semantic versioning rules, bounded context mapping strategies, and the dependency chain from specification to client. These are areas where candidates often have practical experience but find the exam's formal distinctions harder than expected.
– Specifications, assets, and the dependency chain
An API, its specification, its implementation, and its clients form a dependency chain, and the exam tests whether you understand which changes in that chain propagate and which do not. If you change an API specification, you need to know exactly what is affected and what is not. Anypoint Exchange is the mechanism for publishing and sharing reusable assets, and the exam expects you to know what kinds of assets can be published there and how they relate to API specifications. The practical question is always: what breaks when something changes? Candidates who think in terms of loose coupling rather than specific dependency rules tend to pick distractors that sound reasonable but miss the formal boundary the exam is drawing.
– Versioning, bounded contexts, and idempotency
Semantic versioning is rule-based, and the exam will give you a specific change to an API and ask whether it requires a major, minor, or patch version increment. The answer depends on whether the change is breaking for existing clients, and the exam expects you to apply that rule precisely rather than estimate it. Bounded context mapping is the other sharp edge here: given two bounded contexts in a specific power relationship (conformist, customer-supplier, anti-corruption layer, and so on), you need to select the right data model mapping strategy. The power relationship between the contexts determines which side adapts, and picking the wrong strategy in the wrong relationship is a common source of lost marks. Idempotent HTTP methods matter because the exam uses them to test whether you understand which operations are safe to retry. Knowing which HTTP methods are idempotent by specification, and how optimistic concurrency is expressed natively in HTTP, is a small but reliable point of differentiation.
How Designing and sharing APIs is tested
At 10%, this topic generates a mix of scenario and recall items. Semantic versioning questions are recall-heavy: the exam gives you a change description and expects you to classify it correctly. Bounded context questions are scenario-heavy: you get a description of two systems and their relationship, and you must select the appropriate integration strategy. Items reward knowing the formal rules rather than applying intuition. The most common loss of marks comes from treating semantic version increments as a judgment call (this feels like a minor change) rather than a deterministic rule (this breaks existing clients, so it is major). For bounded contexts, candidates who know the pattern names but not the power-relationship implications will pick strategies that fit the wrong context. Idempotency questions are usually brief but precise: the exam expects you to know which HTTP methods carry idempotency guarantees by specification, not by convention. Asset publication questions reward knowing what Exchange can hold and what the publication workflow involves at a high level.
Timed practice against the full ITExamsTopics bank is particularly useful for this topic: semantic versioning and bounded context questions look straightforward until the clock is running, and volume builds the pattern recognition you need to stay accurate under pressure.
The question below turns on one of the versioning or mapping decisions this topic covers. Read the scenario carefully before choosing.
The three-layer model becomes operational here. Earlier topics introduced the tiers conceptually; this topic asks you to apply them to real business processes and data model decisions. At 12%, it is one of the heavier areas, and the marks are spread across layer assignment, data model strategy, and the specific role of DataGraph. Candidates who treat the layers as intuitive categories rather than as a set of assignment rules with defined criteria will find the scenario questions harder than they...
The three-layer model becomes operational here. Earlier topics introduced the tiers conceptually; this topic asks you to apply them to real business processes and data model decisions. At 12%, it is one of the heavier areas, and the marks are spread across layer assignment, data model strategy, and the specific role of DataGraph. Candidates who treat the layers as intuitive categories rather than as a set of assignment rules with defined criteria will find the scenario questions harder than they expect.
– Layer assignment and business process decomposition
Given a business process, you need to identify which APIs are required to implement it and assign each one to the correct layer. The assignment is not aesthetic: it follows the ownership, functional focus, and rate-of-change criteria introduced in Topic 1, now applied at the level of a concrete scenario. The exam will describe a process with multiple steps, backend systems, and consumer channels, and expect you to distribute API responsibilities across the three layers correctly. A System API that leaks process logic, or an Experience API that directly calls a backend, signals a misunderstanding the exam is designed to expose. Candidates lose marks by using the layer names correctly but applying them to the wrong scope of responsibility.
– System API data models and enterprise vs. bounded context models
How a System API's data model relates to its backend system is a design decision with real trade-offs. The exam gives you specific requirements and organizational characteristics and expects you to recommend whether the System API should expose the backend's native model, abstract it, or translate it. Each approach has different implications for coupling and reuse, and the exam tests whether you can match the approach to the stated context rather than defaulting to a preference. The Enterprise Data Model versus Bounded Context Data Model choice is a similar trade-off question at a higher level: you are given a set of APIs and organizational preferences and must select which modelling approach fits. Neither is universally correct, and the exam rewards knowing the conditions under which each one becomes the better answer.
– DataGraph and its appropriate scope
DataGraph allows consumers to query across multiple APIs using a single request, and the exam expects you to know the scenarios where this capability is the right tool and the scenarios where it is not. The key word in the sub-topic is 'suitable': DataGraph is not a general-purpose API aggregation layer, and the exam will present scenarios where it looks attractive but does not fit the requirements. Items reward knowing DataGraph's high-level features well enough to disqualify it when the scenario calls for something it cannot do, or to select it confidently when the scenario fits its strengths. Candidates who treat it as always applicable, or always inapplicable, will lose marks on the boundary cases the exam is specifically constructed to test.
How Designing APIs using System, Process, and Experience Layers is tested
At 12%, this topic produces a significant share of scenario-based items. The exam will describe a business context with multiple systems, consumers, and requirements, then ask you to assign APIs to layers, choose a data model approach, or evaluate the suitability of DataGraph. Items reward the ability to apply the layer criteria systematically rather than by feel. The most reliable source of lost marks is layer boundary confusion: candidates assign process logic to the wrong layer because the scenario makes it ambiguous, and the exam exploits that ambiguity deliberately. For data model questions, items reward matching the approach to the stated organizational characteristics rather than picking the approach that sounds most modern or flexible. DataGraph questions tend to be elimination-based: the exam describes a scenario and the strongest option is the one that correctly identifies whether DataGraph fits. Candidates who cannot articulate DataGraph's specific limitations will struggle to eliminate the wrong options when two of them look reasonable.
The ITExamsTopics practice test spans all layers and data model scenarios, giving you the breadth of item exposure needed to recognise which layer or modelling approach a scenario is pointing toward before you have read all the options.
The question below places you inside a layer-assignment or data model decision. Treat the scenario details as constraints, not background.
At 17%, this is the single heaviest topic on the exam. Governance is where the architecture decisions made in earlier topics are enforced at runtime, and the exam tests that enforcement in detail. You need to know API Manager configuration, policy selection, enforcement strategies, OAuth 2 flows, and client credential management well enough to handle scenarios that combine several of these at once. Candidates who are strong on design but weak on governance mechanics tend to lose their margin here....
At 17%, this is the single heaviest topic on the exam. Governance is where the architecture decisions made in earlier topics are enforced at runtime, and the exam tests that enforcement in detail. You need to know API Manager configuration, policy selection, enforcement strategies, OAuth 2 flows, and client credential management well enough to handle scenarios that combine several of these at once. Candidates who are strong on design but weak on governance mechanics tend to lose their margin here.
– API Manager instances, environments, and policy selection
API Manager uses environments and API instances to separate concerns, and the exam expects you to make appropriate use of that structure based on the nature of the API and the data it handles. Choosing the wrong environment model for a sensitive backend API is the kind of mistake the exam is designed to surface. Policy selection is driven by non-functional requirements: the exam gives you an NFR and expects you to identify which policy or combination of policies satisfies it. The connection between an API specification and the policies applied to it matters too: some policies require changes to the specification itself, and the exam tests whether you can identify exactly what changes are needed and why.
– Enforcement approaches and tier-appropriate security
API policy enforcement can happen through a Mule runtime embedded in the implementation, through an API proxy, through an API gateway, or through Anypoint Service Mesh. The exam gives you a set of preferences and constraints and expects you to select the right enforcement model. Each approach has different implications for where the policy is applied and what the implementation needs to know about it. Security policy selection is further constrained by the API's tier: the appropriate policy for a System API is not the same as for an Experience API, and the exam tests whether you can apply that distinction. Candidates who select policies based on capability alone, without considering tier, will pick answers that are technically valid but architecturally wrong.
– Client credentials, access management, and OAuth 2
Passing client ID and secret to a web API follows specific conventions, and the exam tests whether you know the mechanics: where the credentials go in the request, when they are required, and what happens if they are absent or invalid. Access request and approval workflows in Anypoint Platform have a defined sequence, and revocation has its own mechanics. The exam expects you to know both. OAuth 2 introduces the relationship between Anypoint Platform, external identity providers, API Business Groups, and API clients, and the exam will give you a scenario involving one or more of these and ask you to trace the authorization flow correctly. Candidates who conflate OAuth 2 scopes with API policies, or who misplace the role of the identity provider, reliably lose marks in this area.
– Custom policies and non-functional security constraints
Standard policies cover most NFRs, but the exam includes scenarios where none of the built-in options fits the stated requirement. Identifying when a custom policy is the right answer, rather than a workaround, requires knowing the boundaries of the standard policy library well enough to recognize a gap. Non-functional security constraints on API invocations (rate limiting, IP filtering, threat protection, and similar) each map to specific policies, and the exam expects precise selection rather than a general security posture. The trap is reaching for a broadly applicable policy when the scenario's constraints point to a narrower, more specific one. Items reward knowing not just what a policy does but the exact conditions under which it is the strongest choice.
How Governing web APIs on Anypoint Platform is tested
With 17% of the exam weight concentrated here, this topic will determine a significant portion of your score. Items are predominantly scenario-based and frequently combine two or more governance concerns in a single question: a security requirement, a tier constraint, and an enforcement preference might all appear in the same stem. Items reward the ability to hold multiple constraints simultaneously and find the option that satisfies all of them rather than most of them. The most common source of lost marks is policy selection: candidates pick a policy that addresses the NFR but ignores the tier, or that enforces security but requires a specification change they have not accounted for. OAuth 2 questions reward tracing the authorization flow step by step; candidates who rely on a general understanding of OAuth rather than the specific Anypoint Platform implementation of it will be caught by the distractors. Custom policy questions reward knowing the standard library's limits. Working through a high volume of governance items before the exam is the most direct way to build the pattern recognition this topic demands.
Because this topic carries the most weight, it also has the most to gain from targeted practice. The ITExamsTopics bank lets you filter by topic and run governance items repeatedly until your miss rate drops to a level you trust.
The question below draws on one of the enforcement or access management scenarios this topic covers. Read every constraint in the stem before selecting.
Governance defines what an API must do; this topic covers how the implementation is built, connected, and shipped. At 11%, it spans auto-discovery, VPC requirements, runtime plane hosting options, and the DevOps pipeline that moves code from a developer's machine to a managed environment. The exam tests these as a connected set of decisions, not as isolated configuration steps. Candidates who have hands-on Mule development experience sometimes underestimate this topic because they assume familiarity, then lose marks on the architectural...
Governance defines what an API must do; this topic covers how the implementation is built, connected, and shipped. At 11%, it spans auto-discovery, VPC requirements, runtime plane hosting options, and the DevOps pipeline that moves code from a developer's machine to a managed environment. The exam tests these as a connected set of decisions, not as isolated configuration steps. Candidates who have hands-on Mule development experience sometimes underestimate this topic because they assume familiarity, then lose marks on the architectural boundary questions.
– Auto-discovery, VPCs, and runtime plane hosting
Auto-discovery links a running Mule application to an API instance in API Manager, and the exam tests whether you know what is required on both sides to make that link work and what breaks when the configuration is wrong. Anypoint VPC is not always necessary, and the exam will give you a set of requirements and expect you to identify the ones that actually call for a VPC rather than a simpler network configuration. Runtime plane hosting options carry different trade-offs around operational control, network access, and compliance, and this topic revisits that decision at the implementation level, where the consequences are more concrete than they were in Topic 2. The exam expects you to compare options and select the one that fits a stated set of constraints.
– Testing strategies and DevOps pipelines
MUnit is Mule's native testing framework, and the exam tests where it belongs in a testing strategy rather than how to write tests with it. The distinction between unit and integration tests matters here because the exam will give you a testing requirement and ask you to select the right level, and MUnit is not always the answer. Automated build, test, and deployment pipelines for Mule applications follow the same CI/CD principles as other platforms, but with Anypoint-specific tooling at key steps. The exam expects you to describe the options for automating these steps in a DevOps setting, including what Anypoint Platform provides natively and where external tooling is typically used. Candidates who think of DevOps as a general concept rather than a set of specific Anypoint-compatible options will find the scenario questions harder than expected.
How Architecting and deploying API implementations is tested
At 11%, this topic produces a mix of recall and scenario items. Auto-discovery and VPC questions tend to be precise: the exam gives you a specific configuration or requirement and expects you to identify what is needed or what is wrong. Runtime plane hosting questions are comparative: you get two or more options and must select the one that best fits the stated constraints. Testing questions reward knowing the boundary between MUnit's appropriate scope and the scope of integration or end-to-end testing. DevOps pipeline questions reward knowing which steps in a Mule application's lifecycle can be automated and with what tooling. The most common loss of marks comes from over-applying MUnit (treating it as the answer to all testing questions) or from treating runtime plane options as equivalent when the scenario has a constraint that differentiates them. Candidates who can trace the path from code commit to managed API endpoint, step by step, will handle the DevOps items more reliably than those who think at the pipeline level only.
The ITExamsTopics practice test includes items across all deployment and testing scenarios in this topic. Attempting them under timed conditions reveals whether your knowledge holds up when you cannot pause to look something up.
The question below focuses on one of the deployment or testing decisions this topic addresses. Consider all the constraints before committing to an answer.
CloudHub is Anypoint Platform's managed cloud runtime, and this topic goes well beyond 'deploy and forget.' At 11%, it demands that you understand CloudHub's internal architecture well enough to predict reliability and performance outcomes, avoid single points of failure, and make informed choices about worker sizing, load balancing, and networking. Candidates who have deployed to CloudHub professionally sometimes find the exam harder than expected because the exam tests edge cases and failure modes, not happy-path deployments. – Object Store, worker...
CloudHub is Anypoint Platform's managed cloud runtime, and this topic goes well beyond 'deploy and forget.' At 11%, it demands that you understand CloudHub's internal architecture well enough to predict reliability and performance outcomes, avoid single points of failure, and make informed choices about worker sizing, load balancing, and networking. Candidates who have deployed to CloudHub professionally sometimes find the exam harder than expected because the exam tests edge cases and failure modes, not happy-path deployments.
– Object Store, worker sizing, and reliability characteristics
Object Store in CloudHub is the right solution for specific scenarios, and the exam tests whether you can identify those scenarios rather than defaulting to it as a general state-management tool. Worker size and count are not arbitrary configuration choices: the exam gives you a workload description and expects you to select the configuration that meets it. Reliability and performance in the shared worker cloud depend on the number of regions and the worker configuration, and the exam will give you a deployment description and ask you to predict what happens under load or during a failure. Candidates who treat worker sizing as a cost question rather than an architectural one will miss the reliability implications the exam is looking for.
– Load balancers, networking, and single points of failure
The Shared Load Balancer and the Dedicated Load Balancer serve different purposes and have different capabilities around SSL termination, URL routing, and isolation. The exam tests the defining differences between them, not just a general preference for one over the other. CloudHub networking becomes more complex when customer-owned Amazon VPCs or on-premises data centers are involved, and the exam gives you a topology and expects you to identify the correct networking configuration. Single points of failure in CloudHub deployments are a specific exam concern: the exam will describe a deployment and ask you to identify where a failure would take down the API or to select the configuration that eliminates that risk. Candidates who think about availability in general terms rather than in terms of CloudHub's specific failure domains will pick answers that sound safe but leave a gap.
How Deploying API implementations to CloudHub is tested
At 11%, this topic generates scenario items that require you to reason about CloudHub's architecture rather than recall its configuration options. Reliability and performance questions ask you to predict outcomes from a described deployment: items reward knowing how the shared worker cloud behaves across regions and what happens when a worker goes down. Load balancer questions reward knowing the specific capabilities that differentiate the Shared and Dedicated options, not just their names. Networking questions reward the ability to trace a connection path through a topology that includes customer-owned VPCs or on-premises systems and identify where a configuration gap would cause a failure. Single-point-of-failure questions are elimination-based: the exam describes a deployment and the strongest option is the one that correctly identifies or removes the failure risk. Object Store questions reward knowing the conditions under which it is the appropriate choice, which means also knowing when it is not. Candidates who prepare by reading documentation rather than reasoning through failure scenarios will find the prediction-style items harder than expected.
Seeing a wide variety of CloudHub deployment scenarios in the ITExamsTopics bank before the exam helps you build the mental models needed for the prediction-style questions, which are difficult to prepare for by reading alone.
The question below presents a CloudHub deployment scenario. Think through the failure modes and capacity implications before selecting.
Quality in the context of this exam means measurable runtime behaviour: how an API handles state, how it recovers from failures in its dependencies, and how it scales under load. At 10%, this topic has only three sub-topics, but each one carries enough nuance to generate items that trip up candidates who think in terms of general best practices rather than specific trade-offs. The exam will give you a scenario with stated requirements and expect you to select the approach...
Quality in the context of this exam means measurable runtime behaviour: how an API handles state, how it recovers from failures in its dependencies, and how it scales under load. At 10%, this topic has only three sub-topics, but each one carries enough nuance to generate items that trip up candidates who think in terms of general best practices rather than specific trade-offs. The exam will give you a scenario with stated requirements and expect you to select the approach that meets them, not the one that sounds most resilient.
How Meeting API quality goals is tested
Items in this topic are scenario-driven and trade-off-oriented. Object Store versus caching questions give you a scenario with specific state-management requirements and expect you to identify which mechanism fits and why; the exam exploits the similarity between the two to construct distractors that are almost right. Resilience strategy questions describe a client-side failure scenario and expect you to select the pattern (retry, circuit breaker, fallback, and similar) that addresses it correctly; items reward knowing which strategy applies to which failure mode rather than applying all strategies to all failures. Horizontal scaling questions are the most analytical: the exam describes an API's workload characteristics and asks whether adding instances will improve response time, throughput, both, or neither. Items reward understanding the conditions under which horizontal scaling helps (throughput-bound workloads with stateless implementations) and the conditions under which it does not (latency-bound workloads or stateful implementations that cannot distribute). Candidates who default to 'scale horizontally' as a universal answer will lose marks on the scenarios where it is the wrong call. The topic rewards precise, conditional reasoning over general architectural preference.
If you want to check a specific weak area in this topic rather than re-reading the material, the ITExamsTopics practice test lets you work through quality-focused items in isolation and see exactly where your reasoning breaks down.
The question below asks you to apply one of the quality strategies covered in this topic to a specific scenario. The details matter.
An application network you cannot observe is one you cannot operate. This final topic at 12% covers how Anypoint Platform generates, collects, and surfaces operational data, and how you translate that data into actionable alerts. The exam does not treat monitoring as an afterthought: it expects you to specify alerts at the right level of granularity for each layer of API-led connectivity and for Mule applications directly. Candidates who have operated Mule in production sometimes underestimate how precisely the exam...
An application network you cannot observe is one you cannot operate. This final topic at 12% covers how Anypoint Platform generates, collects, and surfaces operational data, and how you translate that data into actionable alerts. The exam does not treat monitoring as an afterthought: it expects you to specify alerts at the right level of granularity for each layer of API-led connectivity and for Mule applications directly. Candidates who have operated Mule in production sometimes underestimate how precisely the exam tests alert specification.
– Platform monitoring components and API invocation metrics
Several components of Anypoint Platform generate data that feeds monitoring and alerting, and the exam expects you to identify which component produces which kind of data. Conflating the source of a metric with the tool that displays it is a reliable way to pick the wrong answer. API invocation metrics are a specific set of measurements: the exam expects you to know what Anypoint Platform collects for each invocation, at what granularity, and what each metric tells you about API behaviour. Candidates who think of metrics in general observability terms rather than in terms of the specific measurements Anypoint Platform exposes will struggle with questions that require precise identification.
– Alert specification for APIs and Mule applications
Specifying alerts is an architectural decision, and the exam treats it as one. For API invocations, the exam expects you to define appropriate alerts for key metrics across all three layers of API-led connectivity: the right threshold or condition for a System API alert may be different from the right one for an Experience API, because the failure modes and SLA implications differ by layer. For Mule applications, alerts operate at the application level rather than the API invocation level, and the exam tests whether you understand that distinction and can specify alerts that are meaningful rather than noisy. The trap is specifying alerts that are too broad (alerting on everything) or too narrow (alerting only on the consumer-facing layer). Items reward the ability to match an alert specification to the operational risk it is designed to surface, and to do that consistently across all layers.
How Monitoring and analyzing application networks is tested
At 12%, this topic generates a mix of identification and specification items. Identification items give you a monitoring scenario and ask which platform component is the source of a specific metric or event; items reward precise knowledge of which Anypoint Platform component is responsible for what, not a general understanding of observability. Specification items give you a set of operational requirements and ask you to define appropriate alerts: items reward knowing both what to alert on and at which layer. Candidates lose marks in two main ways. First, they misattribute metrics to the wrong platform component, which produces wrong answers on source-identification questions. Second, they specify alerts at the wrong layer or at the wrong granularity, which produces answers that address the symptom rather than the risk. The Mule application alert questions are distinct from the API invocation alert questions, and the exam expects you to keep those two categories separate. Candidates who treat monitoring as a single undifferentiated concern rather than a layered set of responsibilities will find the specification questions harder than the identification ones.
The ITExamsTopics practice test covers this topic alongside all others in a single purchase, giving you a complete picture of where your monitoring knowledge stands relative to the rest of the exam before you sit.
The question below asks you to identify or specify a monitoring decision for a described application network. Apply the layer-specific criteria before choosing.
Ready to Start Practicing?
Access all questions and start your exam preparation journey
Upgrade to Full Salesforce Certified MuleSoft Platform Architect (Mule-Arch-201) Exam Questions 🚀


